
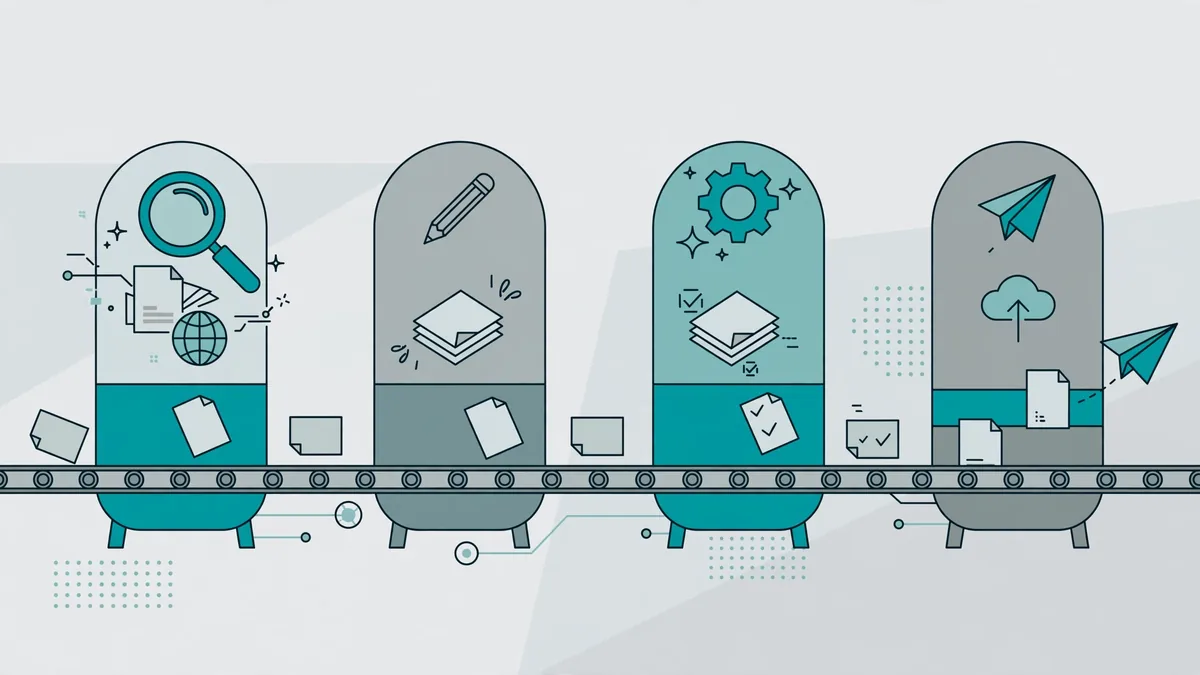
One giant prompt is a gamble: if the output is wrong, you start over. Prompt chaining is the opposite bet — small steps, each one checked before the next begins, like an assembly line instead of a lottery ticket.
Prompt Chaining: Multi-Step AI Workflows Guide (2026)
Prompt chaining is the technique of breaking one complex task into a series of smaller prompts, where the output of each step becomes the input to the next. Instead of asking an AI model to research, outline, draft, edit, and format a report in a single request, you run a chain: a research prompt, then an outlining prompt that consumes the research, then a drafting prompt that consumes the outline, and so on. Each link in the chain does one job well, and you can inspect, validate, or fix the output at every step before it flows downstream.
If you have ever received a long, impressive-looking AI response that quietly drifted off-topic by paragraph four, you have felt the limits of the single “mega prompt.” Large language models do their best work when each request is focused, verifiable, and small enough that the model’s attention stays locked on the actual goal. Prompt chaining takes that insight and turns it into a repeatable engineering practice — one used in everything from customer-support triage systems to automated content pipelines. This guide explains the concept from the ground up, lays out the core chaining patterns, walks through two complete worked examples (a research brief and a content pipeline), and shows how to build chains with no-code tools as well as with code.
What Is Prompt Chaining?
At its simplest, prompt chaining is sequential composition: Step 1 produces intermediate output X, Step 2 takes X and produces Y, Step 3 takes Y and produces Z. The final output Z is the deliverable, but every intermediate product exists as its own artifact you can read, score, edit, or regenerate.
Consider the task “write a competitive analysis of three project-management tools.” A single-prompt approach hands the model that sentence and hopes for the best. A chained approach looks like this:
- Step 1 — Fact gathering: “List the published pricing tiers, key features, and integration lists for Tool A, Tool B, and Tool C, citing each vendor’s pricing page.”
- Step 2 — Structuring: “Given this feature data [output of Step 1], organize it into a comparison table with rows for pricing, integrations, automation limits, and support.”
- Step 3 — Analysis: “Given this table [output of Step 2], identify which tool fits a 20-person remote team and explain why in 300 words, flagging any claim you cannot verify.”
- Step 4 — Formatting: “Given this analysis [output of Step 3], format it as a clean report with headings, the table, and a summary box.”
Nothing about this is exotic — it is the same divide-and-conquer logic behind assembly lines, compiler pipelines, and ETL jobs. The difference is that each stage is a natural-language instruction executed by a language model, which makes chains flexible but also means every stage can introduce errors. That is exactly why chains need quality gates, a topic we will return to later.
How Chaining Differs From a Long Prompt
A long prompt and a chain can contain the same instructions, but they behave differently. In a single long prompt, the model must hold every requirement in working memory simultaneously — tone, structure, facts, length, formatting — while generating thousands of tokens. Research on long-context reasoning consistently shows that models follow instructions more reliably when each request is narrow. In a chain, each prompt carries only the instructions relevant to its own stage plus the intermediate data it needs. The result is measurably better instruction-following, and when something goes wrong you know exactly which stage failed instead of regenerating the entire output and hoping the dice roll differently.
Why Chaining Beats the Mega Prompt
There are five practical reasons teams adopt prompt chaining for production work:
- Error isolation. When Step 2 of 5 produces a bad outline, you regenerate only Step 2. With a mega prompt, one weak paragraph poisons the whole response and you start over from zero.
- Verifiability. Intermediate outputs are small enough to check. You can verify Step 1’s facts against source pages before Step 3 builds analysis on top of them. Chains turn “trust the model” into “trust, but verify at each checkpoint.”
- Reusability. A good “extract key facts” step or “summarize for executives” step can be reused across dozens of workflows. Mega prompts are monoliths; chains are modular.
- Cost and latency control. Not every stage needs the most powerful model. Fact extraction might run fine on a fast, cheap model while the final analysis step uses the strongest one available. Chains let you match model strength to stage difficulty.
- Human-in-the-loop insertion. Chains have natural pause points. A content team can require human approval of the outline (Step 2) before the draft (Step 3) is generated — impossible to enforce inside a single prompt.
The Anatomy of a Reliable Chain
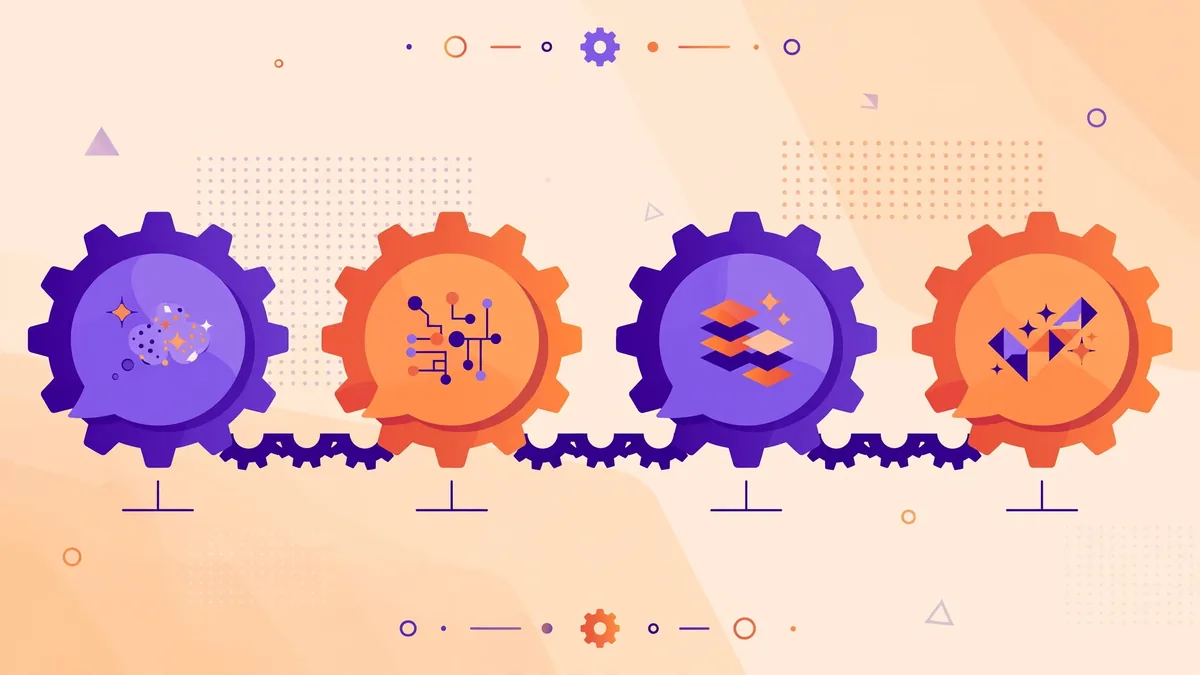
Every robust chain, whether it has three steps or thirty, is built from the same components:
- A defined input contract. Each step declares what it needs: “Input: a bullet list of product features. Output: a 5-row comparison table.” Writing these contracts down — even informally — is the single highest-leverage habit in chain design.
- Self-contained prompts. Each step’s prompt should include everything it needs to do its job. If Step 3 needs the original research data and not just Step 2’s table, pass both along. Relying on “the model remembers earlier steps” is fragile, especially across API calls where each request is stateless.
- Structured intermediate formats. Freeform prose is a poor handoff format. Ask intermediate steps to emit JSON, markdown tables, or labeled sections so the next step can parse them reliably. A Step 1 that returns
{"price": "$20/mo", "limit": "10,000 rows"}is far easier for Step 2 to consume than three paragraphs of marketing-flavored prose. - A validation step. At minimum, one stage should check the work: a “critic” prompt that reviews the draft against the original requirements before it ships. More on this in the quality-gates section.
- Logging. Record each step’s input, output, model, and timestamp. When a chain misbehaves in production, logs are the difference between debugging and guessing.
Core Prompt Chaining Patterns
Chains come in a handful of reusable patterns. Recognizing them lets you design workflows faster and communicate designs to teammates.
Sequential Chaining
The simplest pattern: Step 1 → Step 2 → Step 3, each feeding the next. Use it for any linear production process — research → outline → draft → edit, or extract → transform → summarize. Most beginner chains are sequential, and that is fine; linear workflows cover a large share of real work.
Parallel Decomposition (Fan-Out / Fan-In)
Some tasks split naturally into independent subtasks. Writing a product comparison of five tools? Run five parallel “research tool X” prompts, then fan in with a single “synthesize these five research notes” step. Parallel steps cut wall-clock time dramatically and keep each subtask’s context small. The fan-in step is where most of the design care goes: it needs clear merge instructions (“deduplicate features, normalize pricing to per-user-per-month, flag conflicting claims”).
The Router Pattern
A router step classifies the input and sends it down different sub-chains. A support-ticket chain might route: billing questions → billing answer chain; bug reports → bug-triage chain; feature requests → logging chain. The router prompt itself is small (“Classify this ticket into exactly one category and output JSON”), but it turns one generic workflow into several specialized ones.
The Evaluator / Critic Pattern
A second model call — or the same model with a different prompt — reviews the first output. The critic checks the draft against explicit criteria (“Does every claim cite a source? Is the tone neutral? Is it under 400 words?”) and either approves it or sends it back with specific revision notes. This generator-critic loop is one of the most reliable ways to raise output quality, and it works even when both sides use the same underlying model, because the critic prompt forces a different cognitive stance: judging rather than producing.
Iterative Refinement
Some outputs improve through repeated passes: draft → critique → revise → critique → revise, stopping when the critic approves or a max-iteration cap is hit. Always set the cap (three rounds is a common default) to bound cost and prevent the model from “polishing” good text into worse text — a real failure mode where endless revision loops degrade quality.
Worked Example 1: From Raw Topic to Research Brief
Let us build a complete chain for a realistic task: producing a two-page research brief on “AI scheduling assistants for dental practices.” This is the kind of deliverable a marketing analyst or consultant might need weekly.
Step 1 — Scope definition (router-ish). Prompt: “List the 8 sub-questions a research brief on AI scheduling assistants for dental practices must answer to be useful to a practice manager deciding whether to adopt one. Output as a numbered list.” Why start here? Because the model’s first instinct about what matters often differs from yours, and seeing the scope explicitly lets you edit it before any research happens.
Step 2 — Parallel fact gathering (fan-out). For each sub-question, run: “Answer this sub-question [question] about AI scheduling assistants for dental practices. Base your answer on published vendor documentation, pricing pages, and reputable industry sources. For every factual claim, note the source type (vendor page, review site, industry report). Output as bullet points.” These run in parallel, keeping each call focused on one question instead of all eight.
Step 3 — Fan-in synthesis. Prompt: “Combine these eight answered sub-questions [outputs] into a structured research brief: Executive Summary (150 words), Market Landscape, Pricing Overview (table), Key Vendors, Risks and Limitations, Recommendation. Remove duplicates, resolve contradictions by noting them explicitly, and mark any claim lacking a source as UNVERIFIED.”
Step 4 — Critic pass. Prompt: “Review this research brief [output] against these criteria: (1) every factual claim has a source type or UNVERIFIED tag; (2) the executive summary is ≤150 words; (3) pricing is presented in a table with per-month figures; (4) no marketing superlatives (‘revolutionary,’ ‘game-changing’). List every violation with the exact sentence, then output a corrected version.”
Step 5 — Format. A final light step converts the corrected brief into the house template — headings, a header block with date and topic, and a disclaimer that figures should be confirmed with vendors before purchase decisions.
Notice what this chain buys you: the scope is editable before research, facts are gathered in small verifiable chunks, contradictions surface explicitly instead of being smoothed over, and the critic enforces your standards mechanically. A single prompt saying “write a research brief” can produce something that looks similar, but you would have no idea which parts to trust.
Worked Example 2: A Content Production Pipeline
Now a longer chain typical of a content team publishing weekly explainers — say, a software company producing “how-to” articles for its blog.
Step 1 — Topic expansion. Input: a one-line topic (“automated invoice reminders”). Prompt: “Generate 5 article angles on this topic for an audience of small-business owners, each with a one-sentence description of what the reader will learn. Rank by likely search interest.” A human picks one angle — the first human-in-the-loop gate.
Step 2 — Outline. Prompt: “Create a detailed outline for a 1,500-word article on [chosen angle]. Include H2/H3 headings, 2-3 bullet points per section describing what to cover, and note where an example or statistic is needed (mark these NEEDS-EVIDENCE).”
Step 3 — Drafting (parallel). Each H2 section becomes its own drafting prompt, run in parallel: “Write the section ‘[heading]’ for this article. Cover these points [bullets]. Audience: small-business owners, plain language, no jargon without explanation. Length: 250-350 words.” Parallel drafting keeps each section tight and prevents the model from rushing the ending — a common mega-prompt failure where the conclusion gets two thin sentences.
Step 4 — Evidence fill. For each NEEDS-EVIDENCE marker: “Find or clearly label-as-example the evidence needed here: [marker context]. If you cannot verify a real statistic, write a clearly labeled illustrative example instead — never invent a statistic.” This step deserves emphasis: it is where the chain actively defends against hallucinated numbers.
Step 5 — Assembly and voice pass. Prompt: “Assemble these sections [outputs] into a full article. Smooth transitions between sections, unify terminology (pick one term for the product feature and use it throughout), and ensure the introduction promises exactly what the article delivers.”
Step 6 — SEO and packaging. Prompt: “Given this article [output], produce: an SEO title under 60 characters, a meta description under 160 characters, 5 section-level subheadings optimized for the focus keyword [keyword], and 3 suggested internal link topics.” Splitting packaging from drafting keeps marketing requirements from warping the article’s substance.
Step 7 — Final critic. A checklist review: word count range, keyword placement, no invented statistics, consistent terminology, working transitions. Human editor does the final sign-off.
This seven-step chain looks like more work than “write a blog post,” and in setup terms it is. In practice, it produces drafts that need one editing pass instead of a rewrite, and every stage’s output is reusable — the outline format, the critic checklist, the packaging step — across every article the team produces.
Putting Chains Into Practice
No-Code Options
You do not need to be a programmer to run prompt chains. Several accessible routes exist:
- Multi-turn conversation, done deliberately. The simplest chain is a chat thread where each message is one designed step and you paste prior outputs forward explicitly. It is manual, but it is how most people should prototype a chain before automating it.
- Custom GPTs / Claude Projects / Gemini Gems. These let you bake the chain’s instructions and reference files into a reusable assistant. They handle simple sequential flows well, though branching logic is limited.
- Zapier and Make. Both offer AI steps (OpenAI, Anthropic integrations) inside visual workflow builders. A new form submission can trigger Step 1, store the output in a table, run Step 2, and notify a human at the gate — no code required. Make’s visual router modules map neatly onto the router pattern.
- n8n and similar self-hosted builders. More control over branching, loops, and data transformation between steps; a reasonable middle ground for technical teams that want ownership of their pipeline.
The no-code ceiling is real: complex branching, dynamic iteration caps, and sophisticated error handling eventually want code. But a surprising number of production content and research workflows never need to leave Zapier or Make.
Code-Based Approaches
For programmatic chains, the ecosystem is mature. Frameworks like LangChain and LlamaIndex provide chain primitives (sequential chains, router chains, map-reduce for fan-out/fan-in) plus memory, retries, and observability. Alternatively, plain scripts calling model APIs directly — Python with the OpenAI or Anthropic SDK — are often clearer than a framework for chains under ten steps; each step is a function, intermediate outputs are variables, and the whole pipeline reads top to bottom.
Whichever route you take, three engineering practices matter most: retries with backoff on API failures, structured outputs (JSON mode or function calling) for machine-consumed handoffs, and evals — a small set of test inputs you run through the chain after any prompt change to catch regressions. Chains are software; treat them like software.
Quality Gates and Common Mistakes
Quality Gates: Keeping Chains Honest
Chains amplify both strengths and errors: a hallucinated fact in Step 1 becomes the foundation of Steps 2 through 5. Quality gates are the checkpoints that stop error propagation. The most effective ones, based on widely published prompt-engineering practice, are:
- Source requirements at fact-gathering steps. Require source types or URLs for factual claims in early steps, so later steps inherit citations instead of inventing authority.
- Critic steps before irreversible actions. Any step whose output goes to a customer, gets published, or triggers spending should pass through an evaluator prompt with an explicit checklist.
- Format validation. If Step 2 must emit JSON for Step 3 to parse, validate the JSON programmatically (or with a “repair” prompt) before continuing. A surprising share of chain failures are format failures, not reasoning failures.
- Human gates at high-stakes points. Outline approval, final publish approval, anything involving money or reputation. The chain pauses, a human clicks approve, the chain resumes. No-code tools support this natively with approval modules.
- Canary inputs. Keep 3-5 test inputs with known-good expected outputs. Run them after any prompt edit. If the chain’s answers drift, the edit broke something — revert and investigate.
A useful mental model: every chain should be designed so that its worst failure is boring (a step errors out and retries) rather than dangerous (confident wrong output shipped to a customer).
Common Prompt Chaining Mistakes
- Too many steps. Each step adds latency, cost, and a fresh chance for error. If a three-step chain produces the same quality as a seven-step chain, ship the three-step one. Start minimal and add steps only to fix observed failures.
- Passing everything everywhere. Dumping the entire conversation history into every step bloats context, raises cost, and distracts the model. Pass each step only what it needs.
- No iteration cap. Refinement loops without a max-round limit can cycle indefinitely or degrade good output. Cap at two or three rounds.
- The critic is a rubber stamp. A critic prompt that says “check this is good” approves everything. Critics need explicit, checkable criteria — word counts, required sections, forbidden phrases.
- Ignoring step-level evaluation. Teams often evaluate only the final output. When quality drops, they cannot tell which step regressed. Log and spot-check intermediate outputs.
- Hardcoding model choices. Model capabilities change every few months. Design steps around difficulty (“needs strong reasoning” vs. “simple extraction”) rather than specific model names, so you can swap models as the landscape evolves.
Frequently Asked Questions About Prompt Chaining
How is prompt chaining different from just asking follow-up questions?
Follow-up questions in a chat are informal chaining — you are already doing it when you say “now shorten that” or “now turn it into a table.” Prompt chaining is the deliberate, designed version: each step has a defined input contract, output format, and quality check, and the whole sequence is repeatable. The difference is the same as between cooking from memory and cooking from a tested recipe.
How many steps should a chain have?
As few as possible. Most effective chains have three to seven steps. One step means you are just prompting; more than ten usually means you have steps that could be merged or a workflow that should be split into separate chains. Let observed failures — not ambition — drive step count upward.
Do I need to use different AI models for different steps?
Not necessarily, but it is often economical. Fast, inexpensive models handle extraction, classification, and formatting well; reserve the most capable models for reasoning-heavy steps like analysis and critique. Many teams start with one model everywhere and specialize only where cost or quality data justifies it.
Can prompt chaining reduce AI hallucinations?
It reduces their impact more than their frequency. Small, focused steps hallucinate less than sprawling ones, and source requirements plus critic steps catch many errors that slip through. No chain design eliminates hallucinations entirely — treat every factual claim as provisional until verified, especially in high-stakes domains.
What is the easiest way to start with prompt chaining today?
Prototype in a plain chat thread: write your task as 3-5 sequential prompts, run them one at a time, and paste outputs forward. Save the prompts that work. Once the sequence is stable and you are running it repeatedly, move it into a no-code tool like Make or Zapier, or a simple script. Automate only after the manual version proves its value.
Does prompt chaining work with any AI model?
The technique is model-agnostic — it works with any instruction-following language model from any major provider. Stronger models produce better results at each step, particularly for the reasoning and critic stages, but the structural benefits (error isolation, verifiability, reusability) apply regardless of which model you use.
For building chains in code, the OpenAI Platform docs cover the function-calling primitives you’ll need.
Keep exploring: If you found this guide to prompt chaining useful, read How to Write Better AI Prompts: A Practical Guide, AI Agents Explained: What They Are and How to Use Them, n8n vs Zapier: Best AI Automation Platform 2026 for more practical ways to use prompt chaining.
What is prompt chaining in simple terms?
Prompt chaining is linking AI prompts so each step’s output feeds the next — research, then outline, then draft, then edit. Prompt chaining beats one giant prompt because each step stays focused, and you can inspect and fix intermediate results. Most serious prompt chaining workflows run 3–7 linked steps.
When should I use prompt chaining instead of one prompt?
Use prompt chaining for multi-part tasks where quality matters: content pipelines, data analysis, code generation. If a single prompt gives inconsistent results, prompt chaining usually fixes it by breaking the job into verifiable stages. Simple one-shot questions don’t need prompt chaining.
Which tools support prompt chaining?
Automation platforms and agent frameworks support prompt chaining natively, letting you wire steps visually or in code. Even chat interfaces support manual prompt chaining — paste step one’s output into step two. As prompt chaining matures, expect more tools to offer it as a built-in template.
Conclusion
Prompt chaining is not an advanced trick reserved for AI engineers — it is the natural next step for anyone whose single prompts have started to strain under the weight of complex tasks. By decomposing work into focused steps with clear handoffs, verifiable intermediates, and critic checkpoints, you get outputs that are more accurate, easier to debug, and cheaper to regenerate when something goes wrong. Start with the patterns in this guide — sequential, fan-out/fan-in, router, critic, refinement — prototype your chain in a chat thread using the worked examples as templates, and automate only once the manual version earns its keep. The teams getting the most reliable results from AI in 2026 are not writing better mega prompts; they are building better chains.

Join the discussion
Have a question or a perspective to share?